 VIOLA: Towards Video In-Context Learning with Minimal Annotations
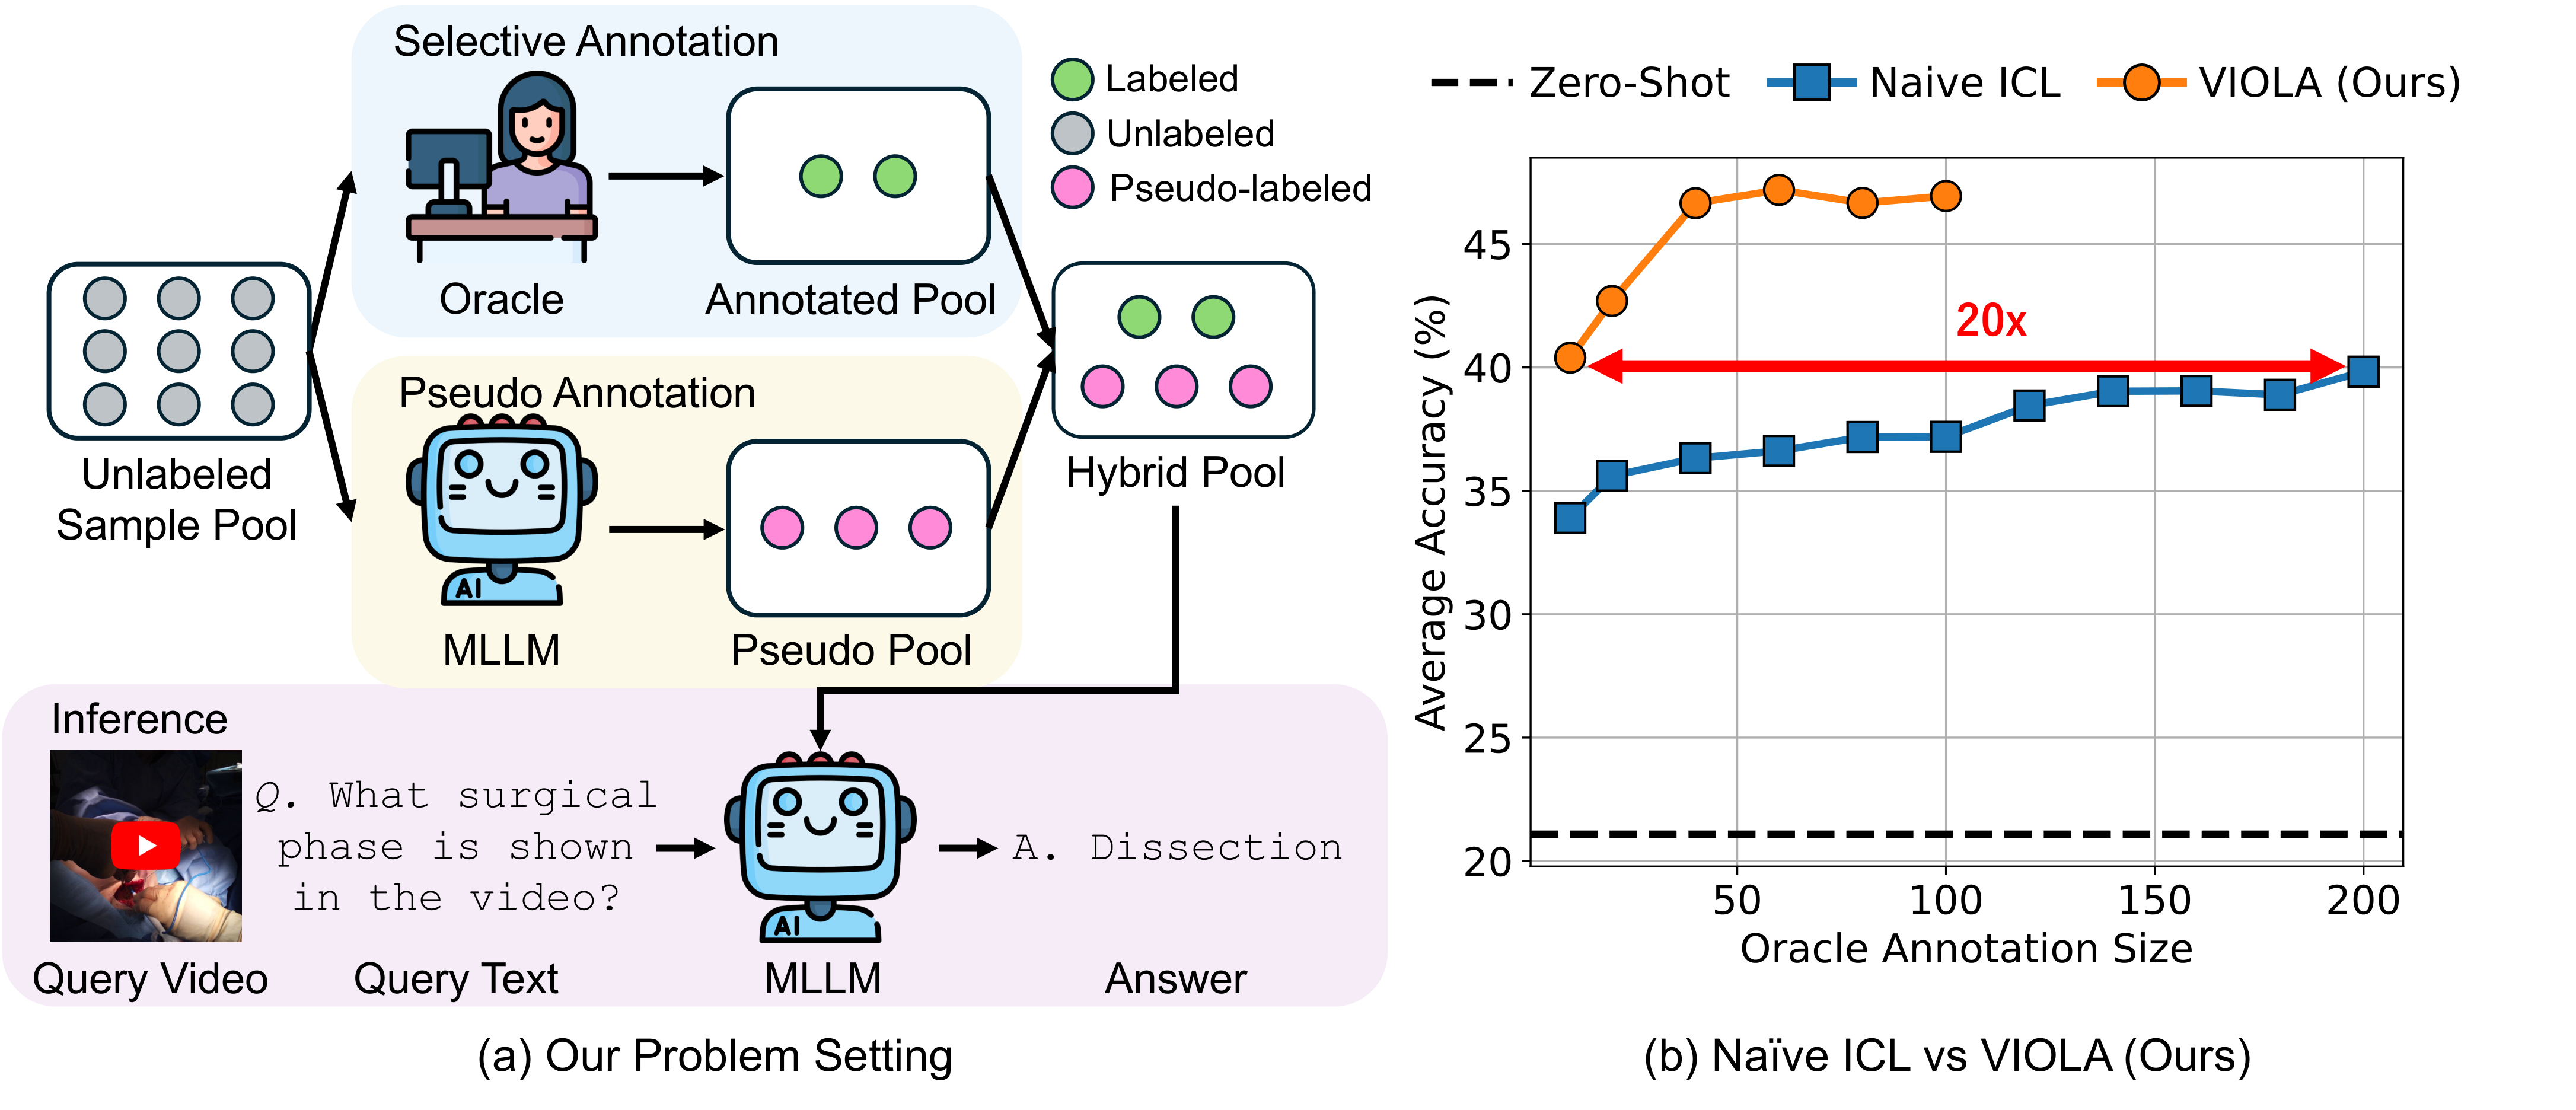
Problem setup and performance. (a) VIOLA selects a minimal subset of informative videos for expert annotation and pseudo-labels the rest, forming a hybrid pool from which demonstrations are retrieved. (b) Compared with Naive ICL (random annotation), averaged over seven classification datasets, VIOLA adapts robustly at much lower annotation cost.
Abstract
Generalizing Multimodal Large Language Models (MLLMs) to novel video domains is essential for real-world deployment but remains challenging due to the scarcity of labeled data. While In-Context Learning (ICL) offers a training-free adaptation path, standard methods rely on large annotated pools, which are often impractical in specialized environments like industrial or surgical settings since they require expert annotations. To bridge this gap, we introduce VIOLA (Video In-cOntext Learning with minimal Annotation), a label-efficient framework that synergizes minimal expert supervision with abundant unlabeled data. First, we propose density-uncertainty-weighted sampling, which uses density estimation to pick samples that are simultaneously diverse, representative, and informative, avoiding visual outliers. Second, to use the remaining unlabeled data without noise propagation, we construct a hybrid pool and introduce confidence-aware retrieval and confidence-aware prompting, which explicitly model label reliability. Experiments across nine benchmarks and four MLLMs show that VIOLA significantly outperforms various baselines in low-resource settings, achieving robust adaptation with minimal annotation costs.
Method
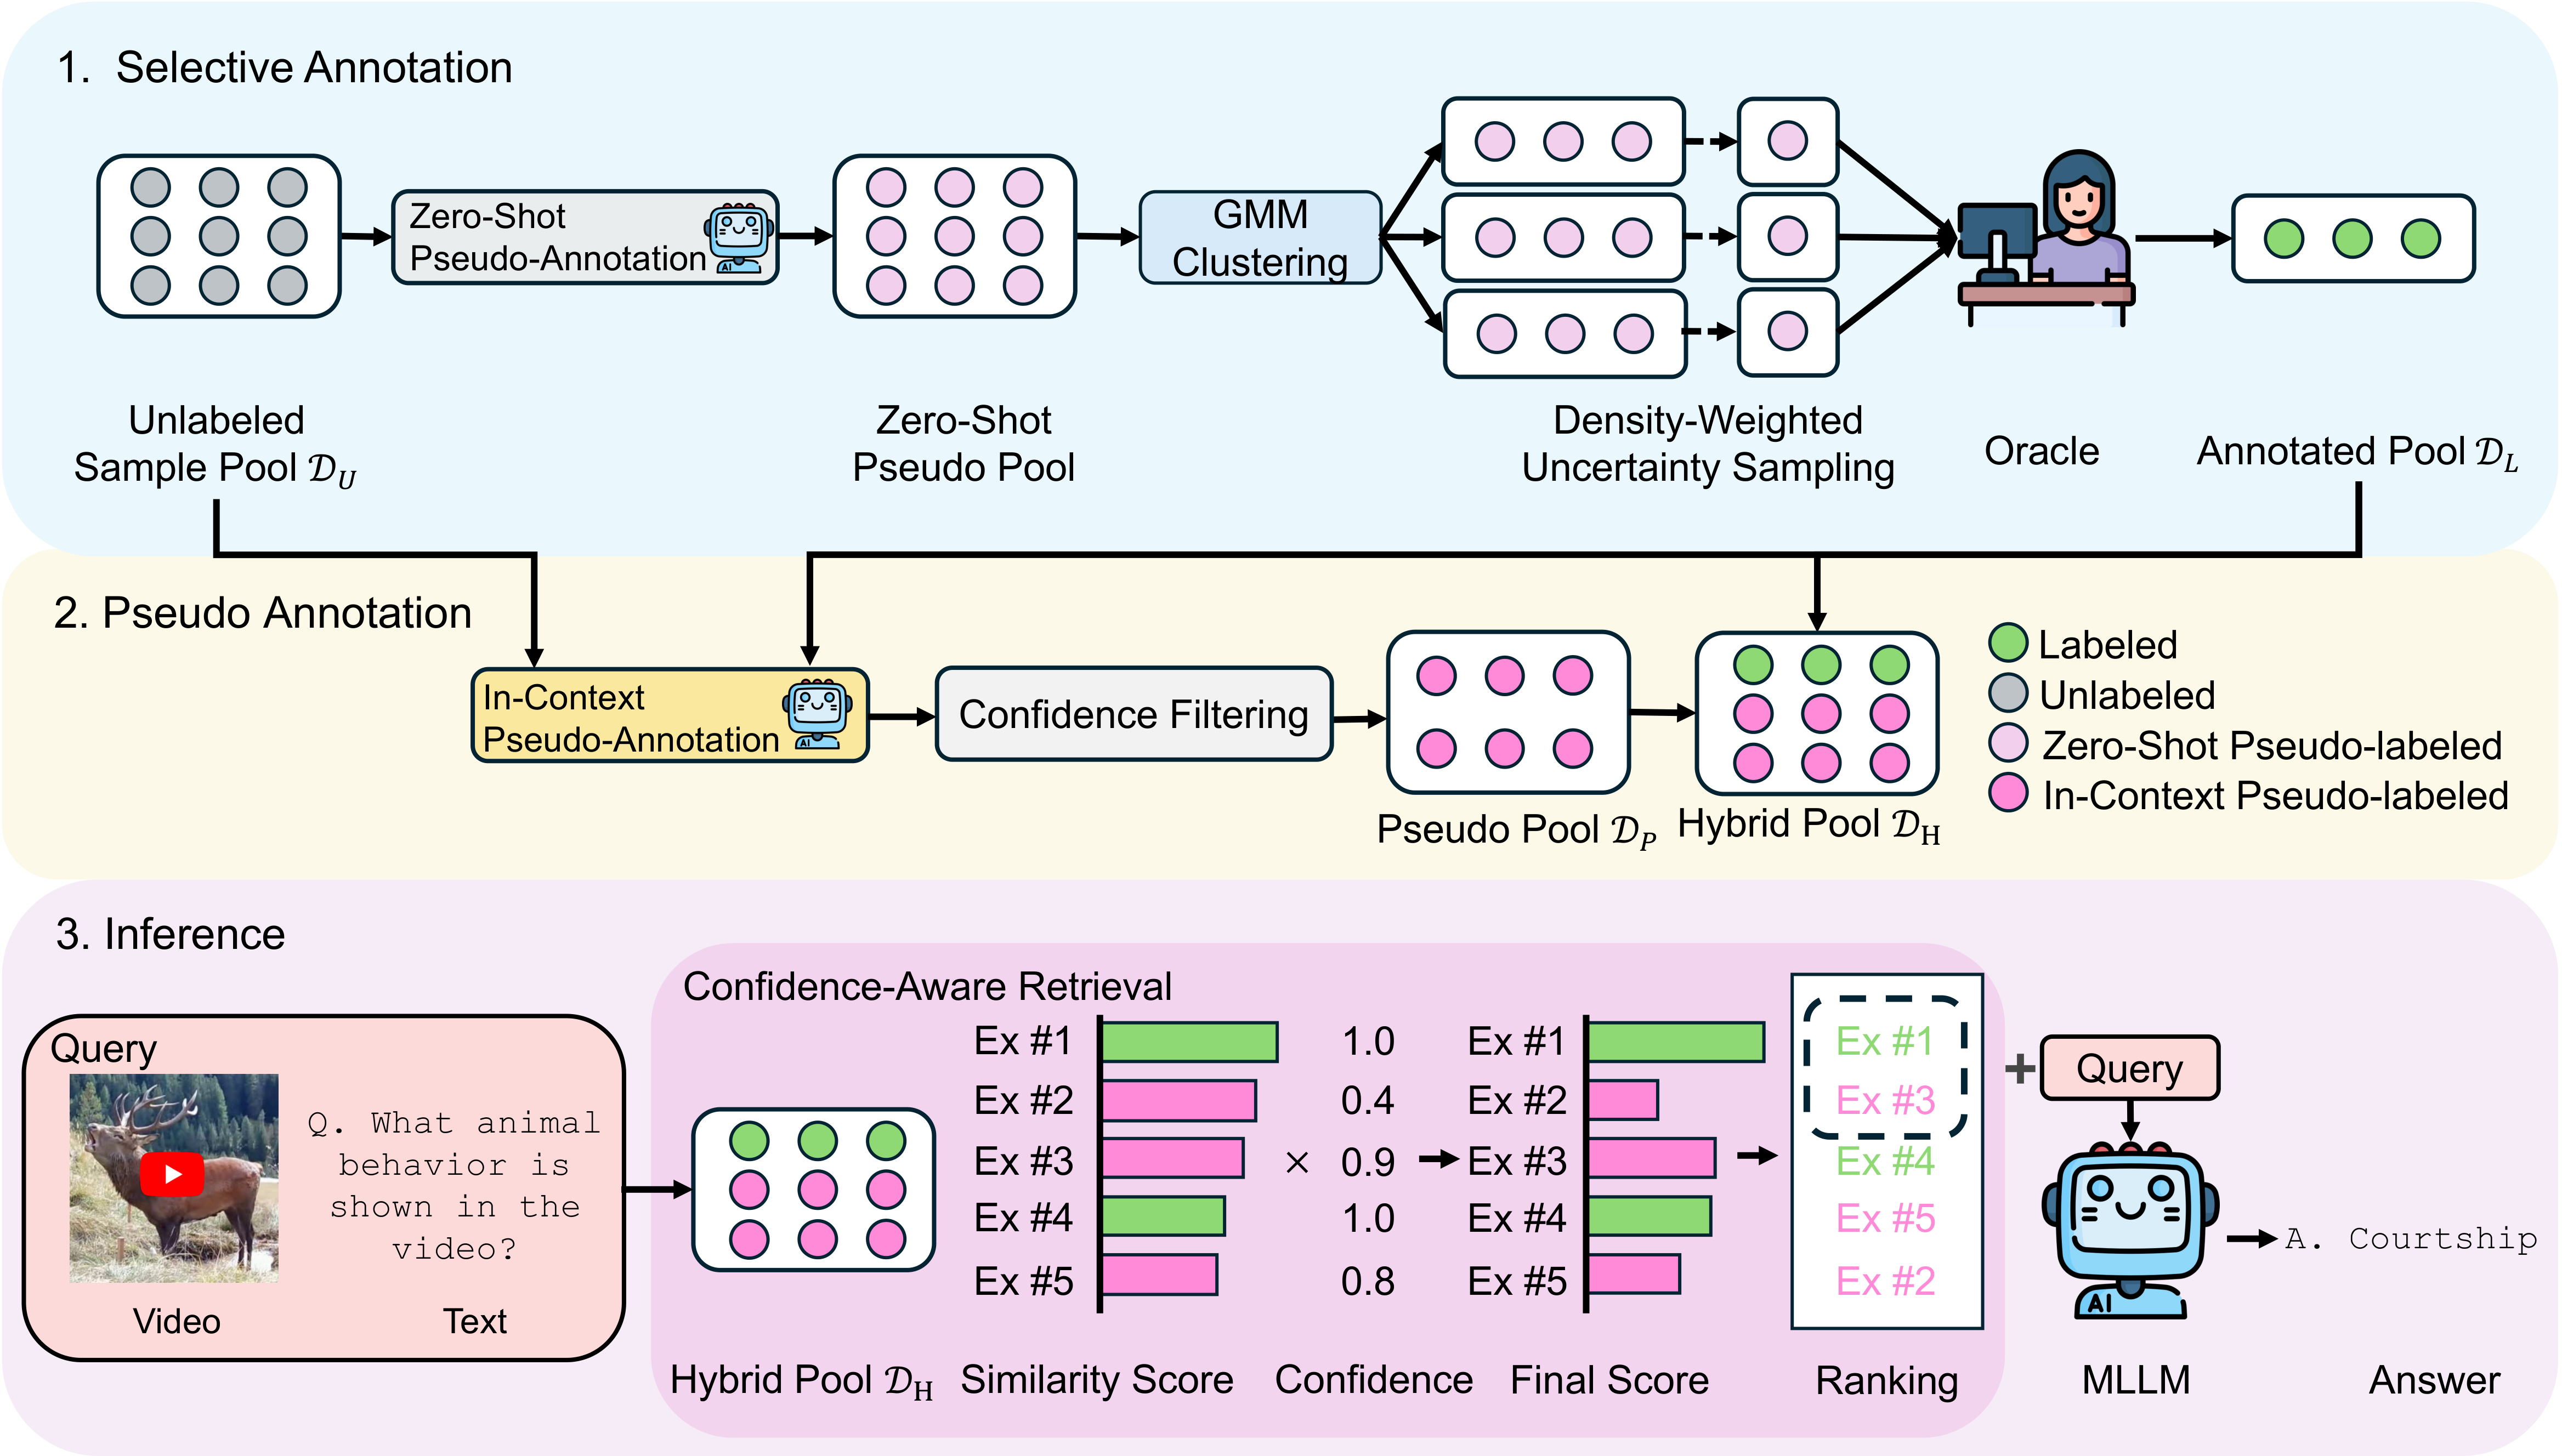
- Density-uncertainty-weighted selection. A GMM partitions the semantic space; within each cluster we pick the sample maximizing uncertainty weighted by density, so expert labels go to samples that are diverse, representative, and informative.
- Confidence-aware retrieval. Demonstrations are retrieved by a composite of visual similarity and label confidence, so limited context slots go to reliable examples.
- Confidence-aware prompting. The label source (ground truth vs. pseudo-label) and its confidence are encoded in the prompt so the MLLM can weigh each demonstration accordingly.
Results
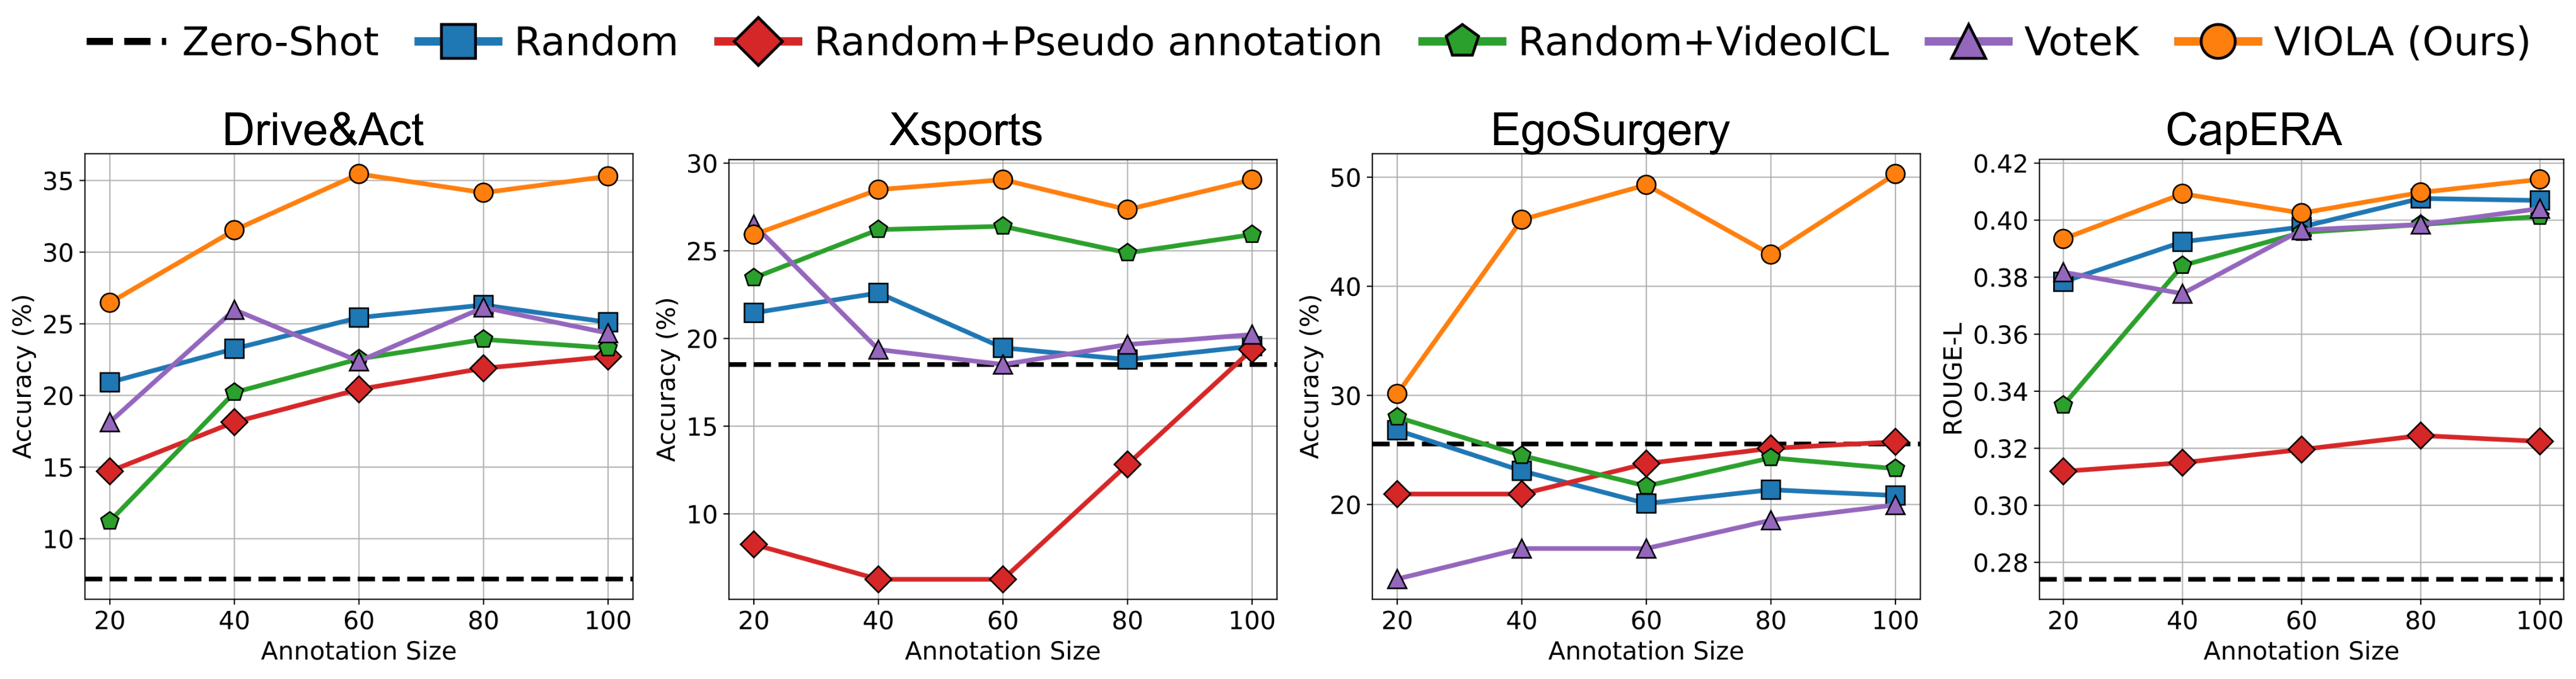
Performance trends under varying oracle annotation budgets. VIOLA vs. baselines with Qwen2-VL-7B, varying the labeled pool size from 20 to 100 samples.
Qualitative Examples
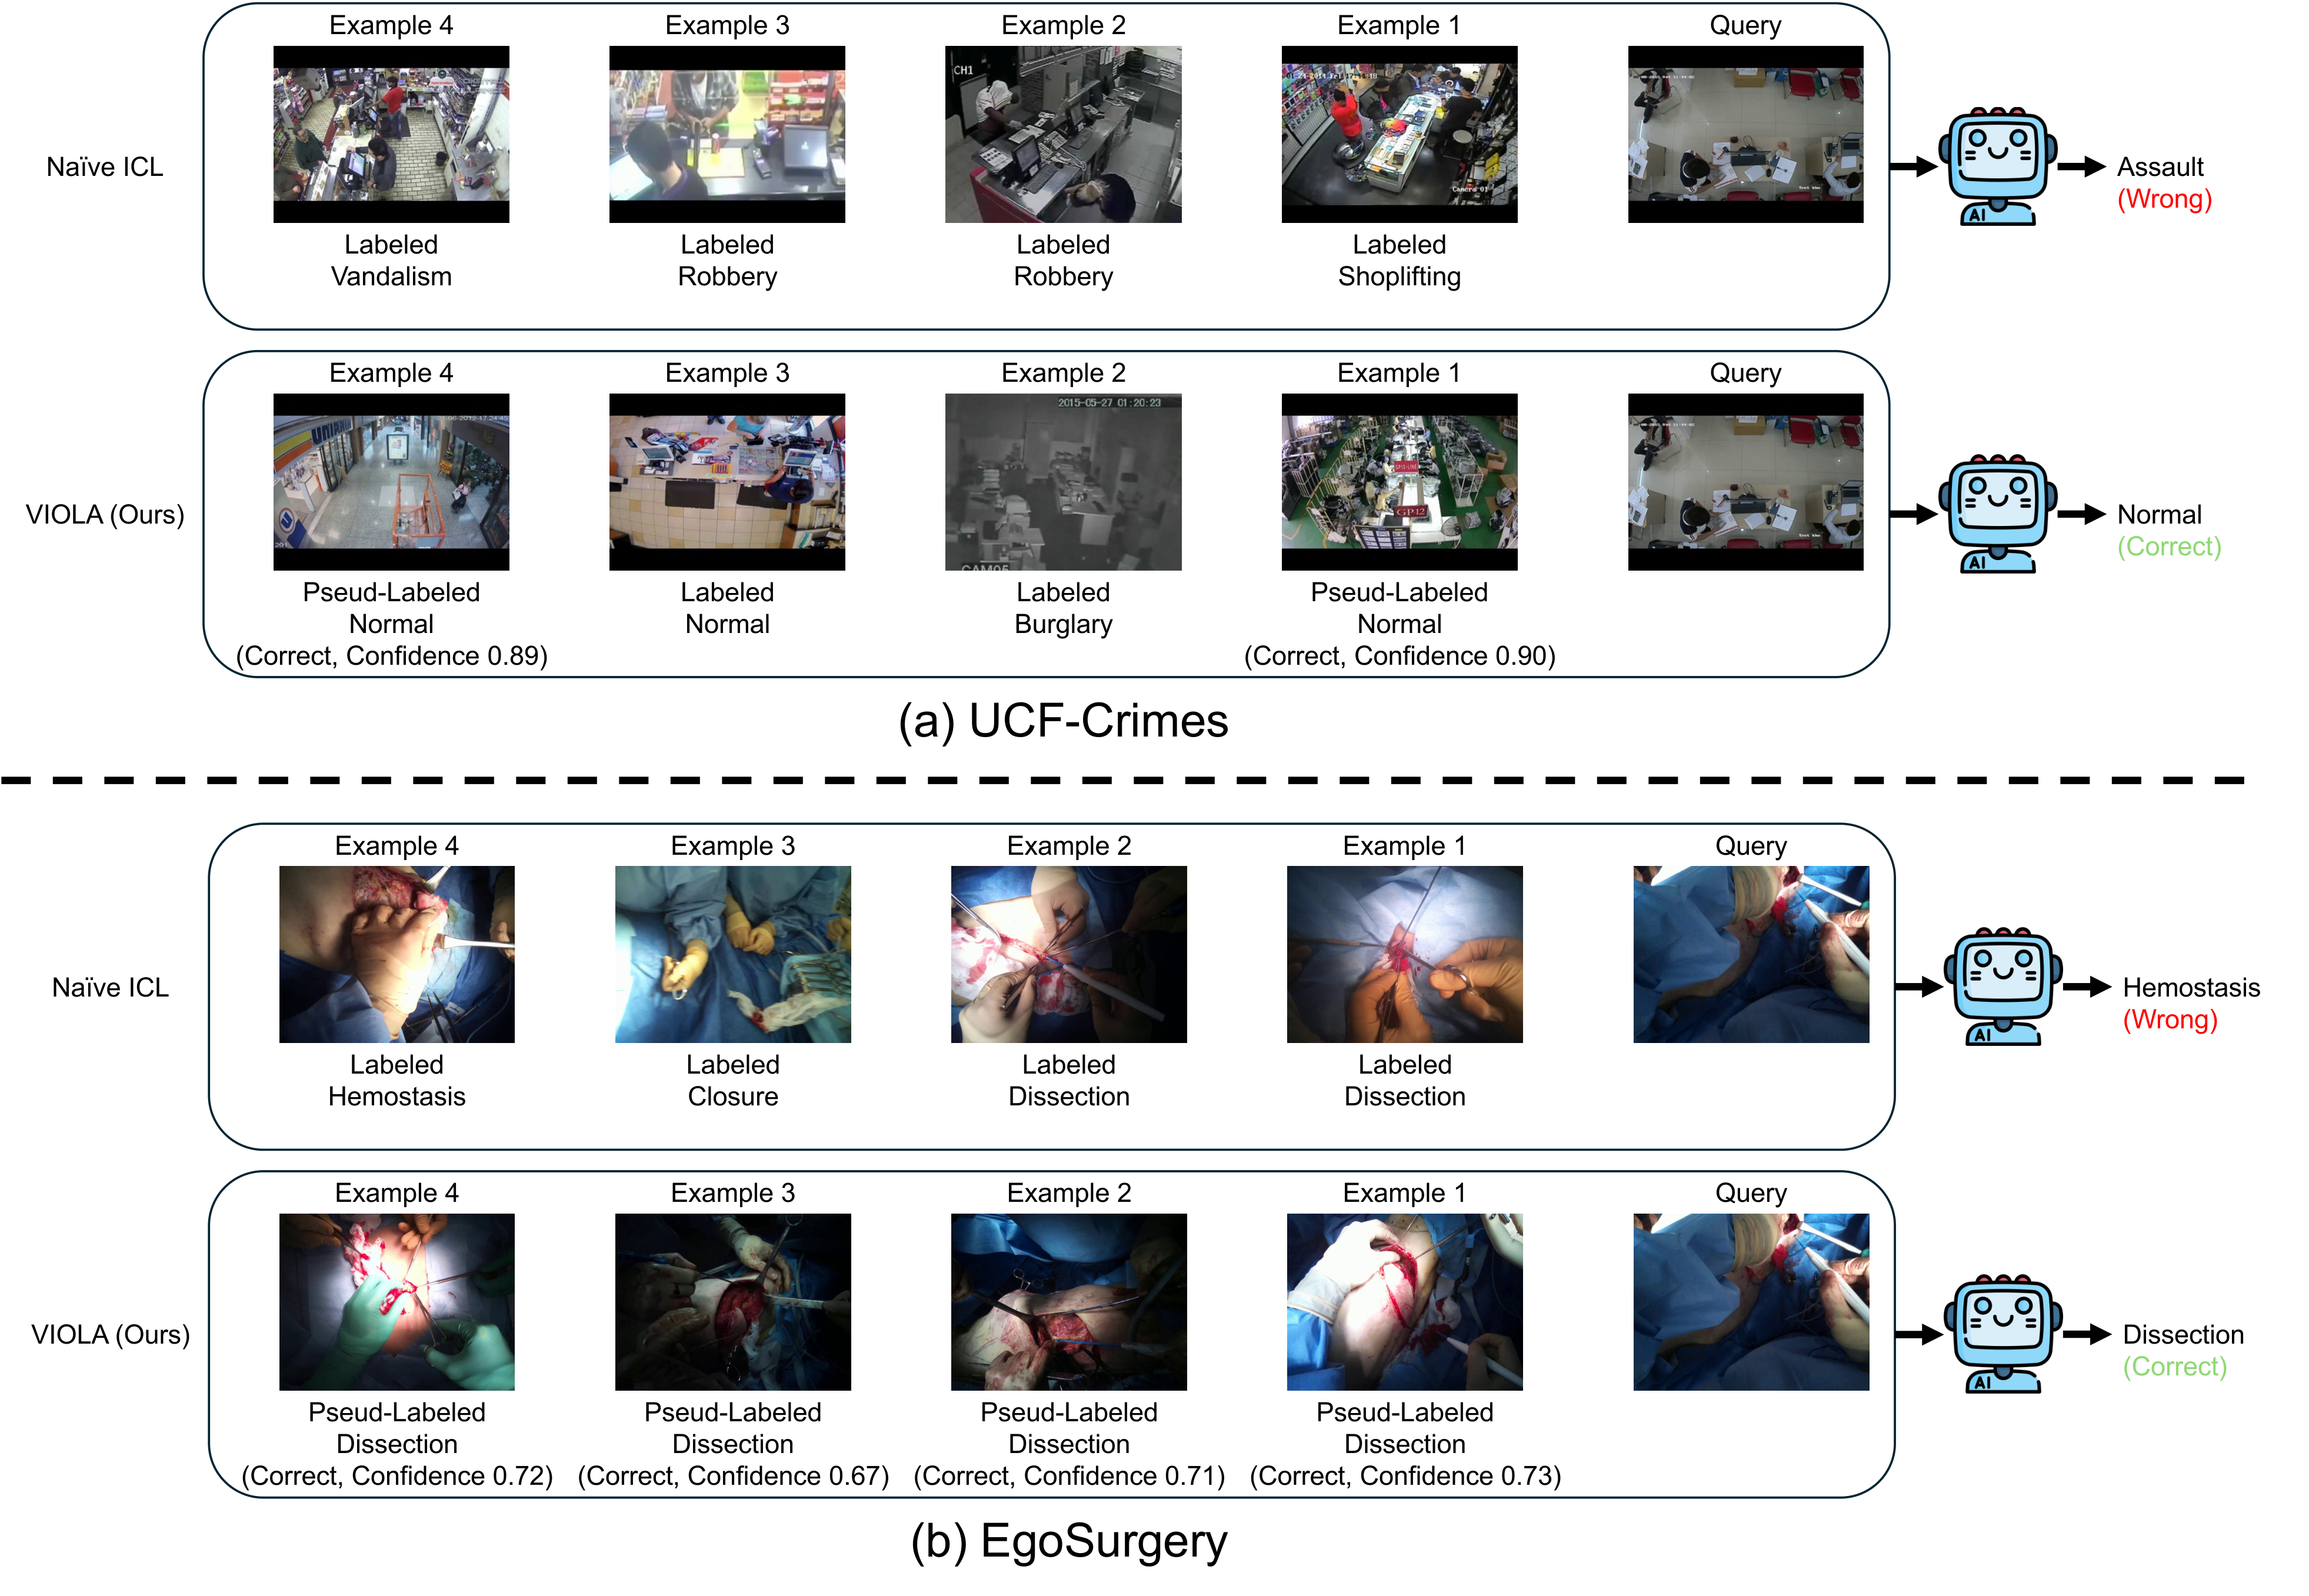
Qualitative results on UCF-Crimes and EgoSurgery.
BibTeX
@inproceedings{fujii2027viola,
  title     = {VIOLA: Towards Video In-Context Learning with Minimal Annotations},
  author    = {Fujii, Ryo and Saito, Hideo and Hachiuma, Ryo},
  booktitle = {IEEE/CVF Winter Conference on Applications of Computer Vision (WACV)},
  year      = {2027}
}